Load Balancing Solutions for Growing Businesses
A slow or unavailable business application rarely affects only the IT team. Customers may abandon a purchase, staff may be unable to complete their work, and operations can fall behind quickly. Load balancing solutions help prevent a single server, application instance, or network path from becoming the point of failure that causes those problems.
For growing organizations, load balancing is not simply a tool for handling high website traffic. It is a practical part of a wider availability, security, and cloud architecture strategy. The right design distributes requests intelligently, supports maintenance without unnecessary disruption, and gives the business a clearer path to scale.
What load balancing solutions actually do
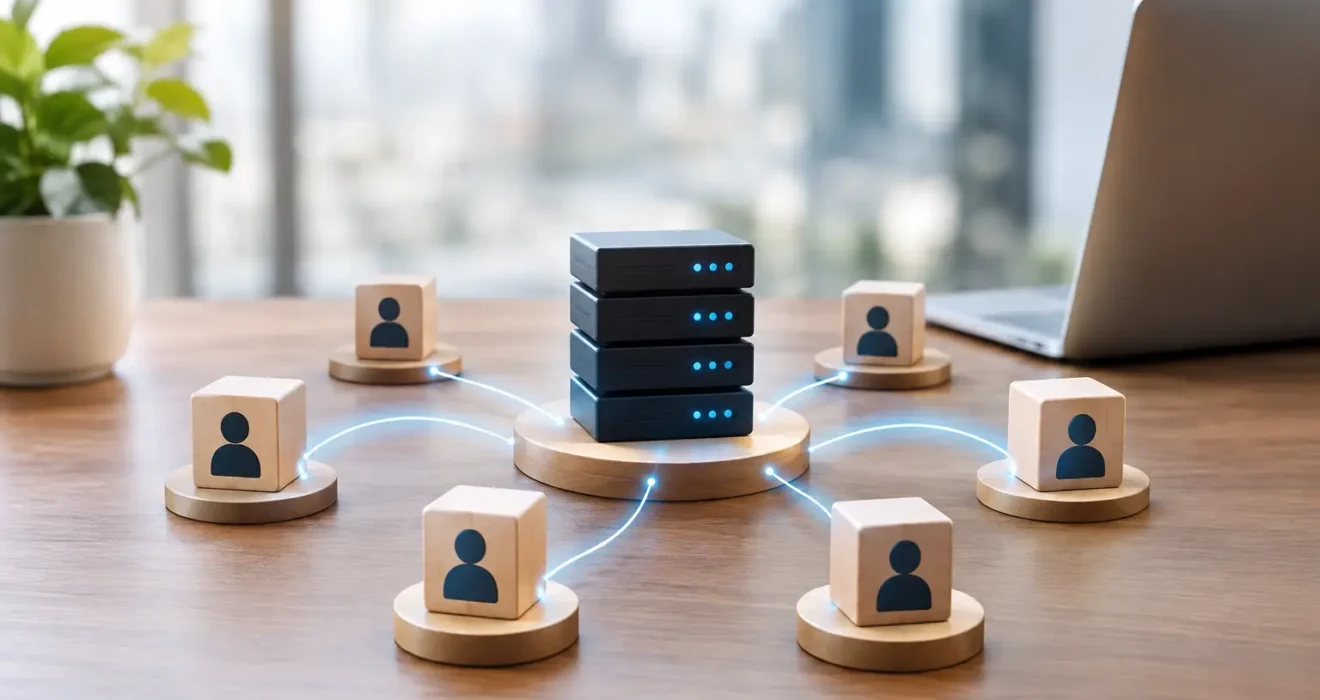
A load balancer sits between users and the systems that respond to their requests. Instead of sending every request to one server, it directs traffic across multiple healthy servers, virtual machines, containers, or application instances.
That distribution can be based on several factors. A simple approach sends requests in rotation. More advanced approaches consider active connections, server response time, geographic proximity, or rules based on the type of request. For example, an organization may send public website traffic to web servers while directing secure application traffic to a separate application tier.
The load balancer also performs health checks. If an application instance stops responding correctly, it can be removed from rotation until it recovers. This is a critical distinction: adding more servers alone does not create high availability if traffic continues to reach a failed server.
A properly planned solution can help with performance, planned maintenance, fault tolerance, and controlled growth. It does not guarantee that every application outage disappears. Database failures, software defects, DNS issues, security incidents, and dependencies on third-party services can still affect availability. Load balancing works best when it is designed alongside monitoring, backups, disaster recovery, and application testing.
When a business needs load balancing
The most obvious signal is inconsistent performance during busy periods. A website may become slow after a marketing campaign, or an internal application may struggle when staff start work at the same time. But peak traffic is not the only reason to consider load balancing.
A business may also need it when a server requires regular maintenance and downtime is difficult to schedule. If the application can run on more than one instance, administrators can update one server at a time while the remaining servers continue serving users. Organizations moving physical servers to cloud infrastructure often use this opportunity to remove single points of failure rather than recreating the same limitations in a new environment.
Security requirements can also drive the decision. Load balancers can terminate encrypted HTTPS connections, enforce modern TLS settings, and integrate with web application firewalls or network security controls. The correct configuration matters. Misconfigured certificates, overly broad firewall rules, or an exposed management interface can create risk even when the architecture looks sophisticated on paper.
Choosing the right type of load balancer
The best option depends on the application, protocol, traffic pattern, recovery objectives, and the skills available to manage it. A small business website has different needs from a customer portal, VoIP service, or line-of-business application used across multiple locations.
Layer 4 versus Layer 7 balancing
Layer 4 load balancing works at the network transport level. It routes TCP or UDP connections based on information such as IP addresses and ports. This approach is useful for services that need fast, straightforward connection distribution and do not require detailed inspection of web requests.
Layer 7 load balancing works at the application level, usually with HTTP or HTTPS traffic. It can make decisions based on hostnames, URL paths, headers, and cookies. For instance, requests to a public website domain can go to one group of servers, while requests to an API path can go to another. This flexibility makes Layer 7 balancing especially useful for modern web applications, APIs, and multi-service environments.
Layer 7 functionality offers more control, but it also requires thoughtful rule design and testing. Complex routing rules can become difficult to troubleshoot if they are not documented and monitored.
Cloud-managed, virtual, and hardware options
AWS and Microsoft Azure provide managed load balancing services that reduce the operational burden of maintaining the load-balancing platform itself. In AWS, organizations may use Elastic Load Balancing services such as Application Load Balancer, Network Load Balancer, or Gateway Load Balancer depending on the workload. In Azure, common options include Azure Load Balancer, Application Gateway, and Front Door, each designed for different network and application delivery scenarios.
Managed cloud services are often a practical choice for businesses already migrating to AWS or Azure. They can integrate with auto-scaling, health monitoring, identity controls, logging, and cloud networking. Costs should still be reviewed carefully, especially where traffic volumes, cross-region data transfer, or advanced security features are involved.
Virtual load balancers can be suitable when an organization needs more control, has hybrid infrastructure, or runs specialized applications. Physical appliances may still make sense in certain data center environments or where specific performance and compliance requirements apply. Neither option is automatically better. The operating model, budget, and recovery requirements should determine the choice.
Design for the application, not just the traffic
A common mistake is treating load balancing as a network-only project. The application must be ready to run across multiple instances. If it stores user sessions only in server memory, users may be logged out or see inconsistent behavior when requests move between servers.
Session persistence, sometimes called sticky sessions, can address this in the short term by directing a user back to the same server. However, it can reduce flexibility during failures and unevenly distribute traffic. A stronger long-term approach is often to store sessions in a shared, secure service or redesign the application so it is stateless where practical.
The same principle applies to uploaded files, scheduled tasks, and database connections. If each server writes files to its own local storage, a user may upload a document and later reach an instance that cannot access it. Shared object storage, shared file services, or a deliberate synchronization strategy may be required.
Databases deserve separate attention. A load balancer in front of web servers does not make the database highly available. Database replication, managed database services, backups, failover processes, and restore testing should be planned according to the business impact of downtime and data loss.
Build security and observability into the design
A load balancer should be placed within a segmented network design. Public-facing traffic can terminate at the load-balancing layer, while application servers remain on private networks without direct public exposure. Access between network tiers should be limited to the ports and systems that are genuinely required.
Encryption should be planned end to end. Some environments terminate TLS at the load balancer and use encrypted traffic again between the load balancer and application servers. Others have different requirements based on internal network controls, compliance needs, and application support. The decision should be documented rather than assumed.
Monitoring provides the evidence needed to know whether the design is working. Track response times, error rates, healthy and unhealthy targets, connection counts, capacity indicators, and changes in traffic patterns. Centralized logs make it easier to investigate incidents and distinguish between a load balancer issue, an application issue, and a downstream dependency failure.
Health checks deserve particular care. A basic check that confirms a server is reachable may not detect an application that is returning errors or cannot reach its database. At the same time, a health check that is too demanding can create unnecessary load or incorrectly remove healthy instances. It should test the right level of functionality for the service.
A practical implementation path
Start by identifying the applications that matter most to customers, staff, and operations. Document current traffic patterns, server dependencies, maintenance windows, and the business impact of an outage. This establishes whether the priority is improved performance, maintenance flexibility, fault tolerance, security, or a combination of these goals.
Next, confirm that the application can operate across multiple instances. Address session handling, shared storage, background jobs, configuration management, and database dependencies before placing a load balancer in front of production traffic. A staged environment is valuable for testing routing rules, certificate renewal, health-check behavior, and failure scenarios without risking normal operations.
Then define a realistic failure plan. Test what happens when an application server fails, when a full availability zone or site is unavailable, and when the database or an external integration becomes unreachable. The response may include automatic failover, a documented manual procedure, or both. What matters is that the recovery approach matches the business requirement and has been tested.
Scotia Logic can help organizations assess current infrastructure, design AWS or Azure architectures, and implement load balancing as part of a broader cloud, security, and continuity plan. A good first step is to review the application’s dependencies and decide which failures the business can tolerate, for how long, and at what cost.